Autonomous RAG / Support SaaS
MyBotGenie
Enterprise RAG chatbot platform featuring automated multi-source ingestion (documents & recursive web crawling), dense/sparse vector retrieval, and BGE cross-encoder reranking for hallucination-free support agents.
Architecture & Overview
Engineering intelligence around real operational constraints.
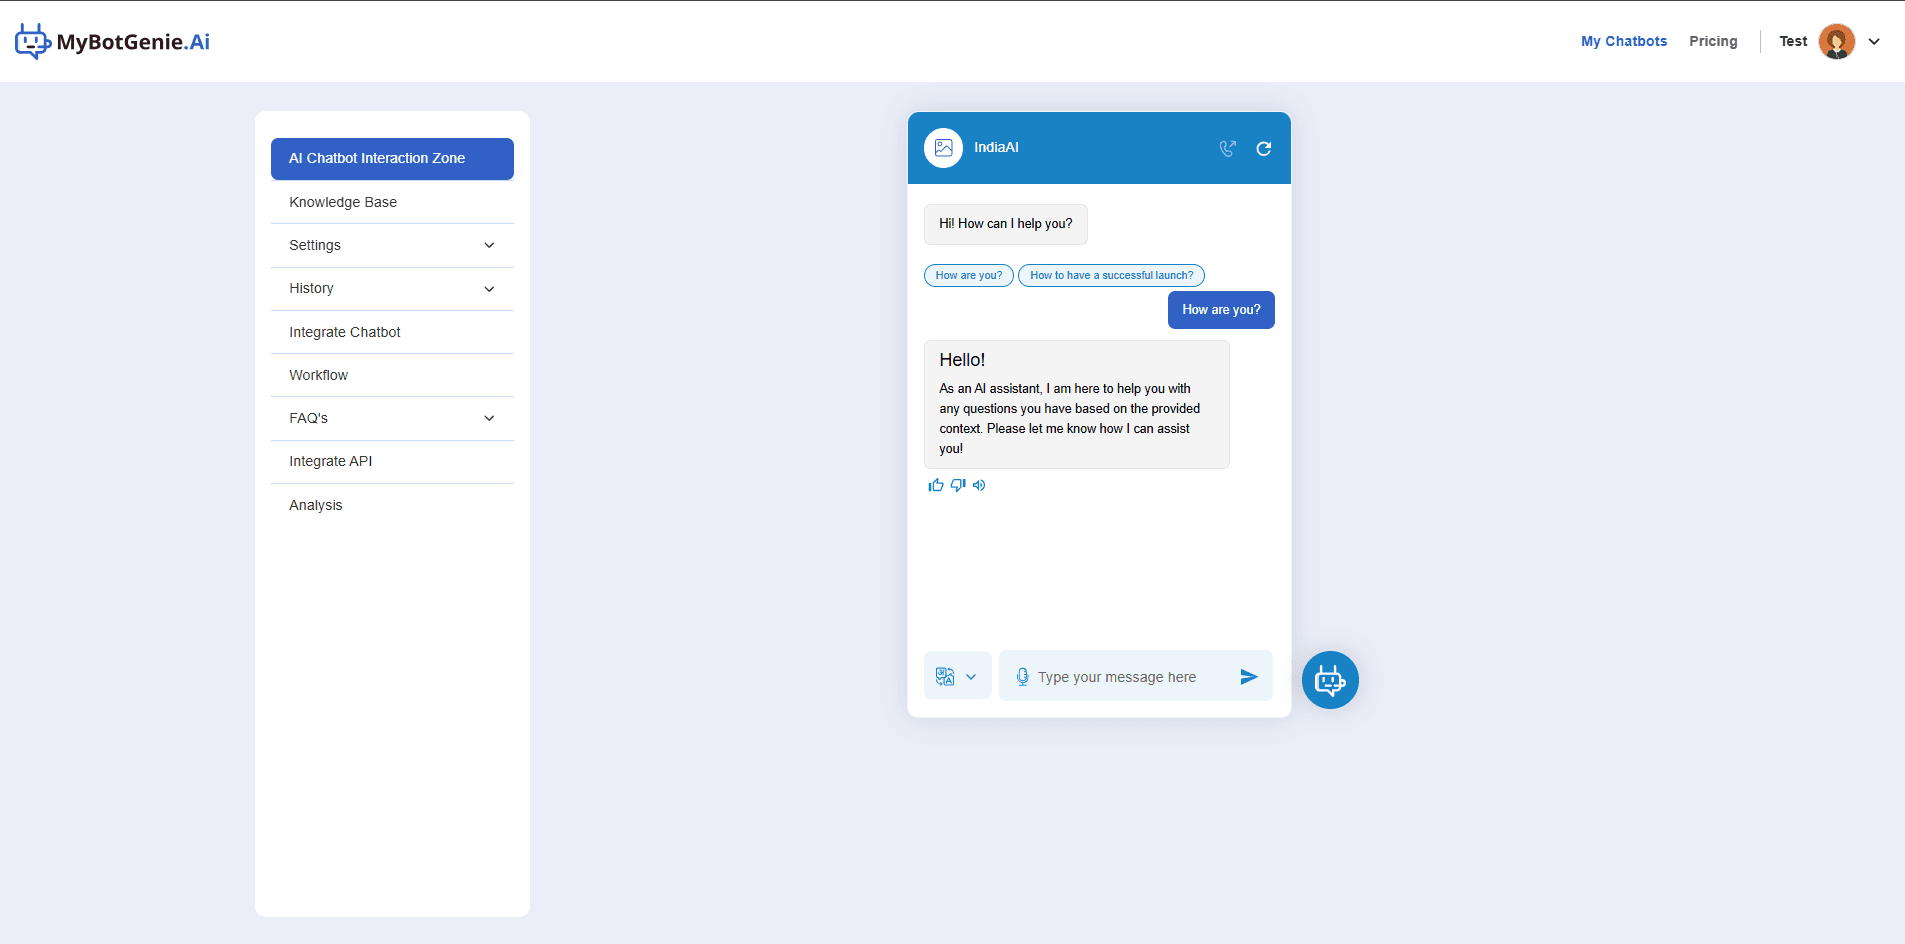
An embeddable AI customer support platform built on a high-precision Retrieval-Augmented Generation (RAG) architecture. The platform continuously ingests multi-source enterprise knowledge—crawling websites via recursive link ingestion and parsing heterogeneous documents (PDFs, DOCX, policies). When a user submits an inquiry, the query is embedded and matched against vector representations using hybrid similarity, then passed through a cross-encoder reranker to discard noisy chunks before the grounded LLM generates an exact, citation-backed response.
Execution Lifecycle
How the System Works End-to-End
Multi-Source Knowledge Ingestion
Automatically crawls web domains, discovers URLs, parses sitemaps, and extracts clean markdown alongside multi-format file uploads (PDF, DOCX, policies).
Semantic Chunking & Vector Indexing
Splits content into context-preserving semantic chunks, generates high-dimensional embeddings, and indexes them for ultra-fast retrieval.
Dense & Sparse Similarity Matching
Performs first-stage candidate retrieval by executing vector similarity search against the enterprise knowledge base.
Cross-Encoder Reranking
Re-scores top candidate chunks using a specialized cross-encoder reranker model to eliminate irrelevant context and guarantee high-precision retrieval.
Grounded LLM Generation & Citation
Prompts the LLM with strict context boundaries to produce hallucination-free answers with verifiable source URLs and document page citations.
Platform Capabilities & Deployment
Engineering Highlights
Capabilities & Guardrails
Product Screenshots